Constitutional Classifiers
Constitutional Classifiers are Anthropic's defense system against universal jailbreaks: input and output classifiers trained on synthetically generated data that filter the vast majority of jailbreak attempts with minimal over-refusals and moderate compute overhead.
Source: Anthropic Research Blog
Attachment: Constitutional Classifiers.pdf
The Problem
LLMs have extensive safety training, but remain vulnerable to jailbreaks (inputs that bypass safety guardrails). Attack types include very long prompts (many-shot jailbreaking), unusual formatting (uSiNg uNuSuAl cApItALiZaTiOn), and many more. These were first described over 10 years ago, yet no fully robust defense has existed in production.
Anthropic needs robust jailbreak defense to safely deploy increasingly capable models under their Responsible Scaling Policy, particularly for models passing the CBRN (chemical, biological, radiological, nuclear) capability threshold.
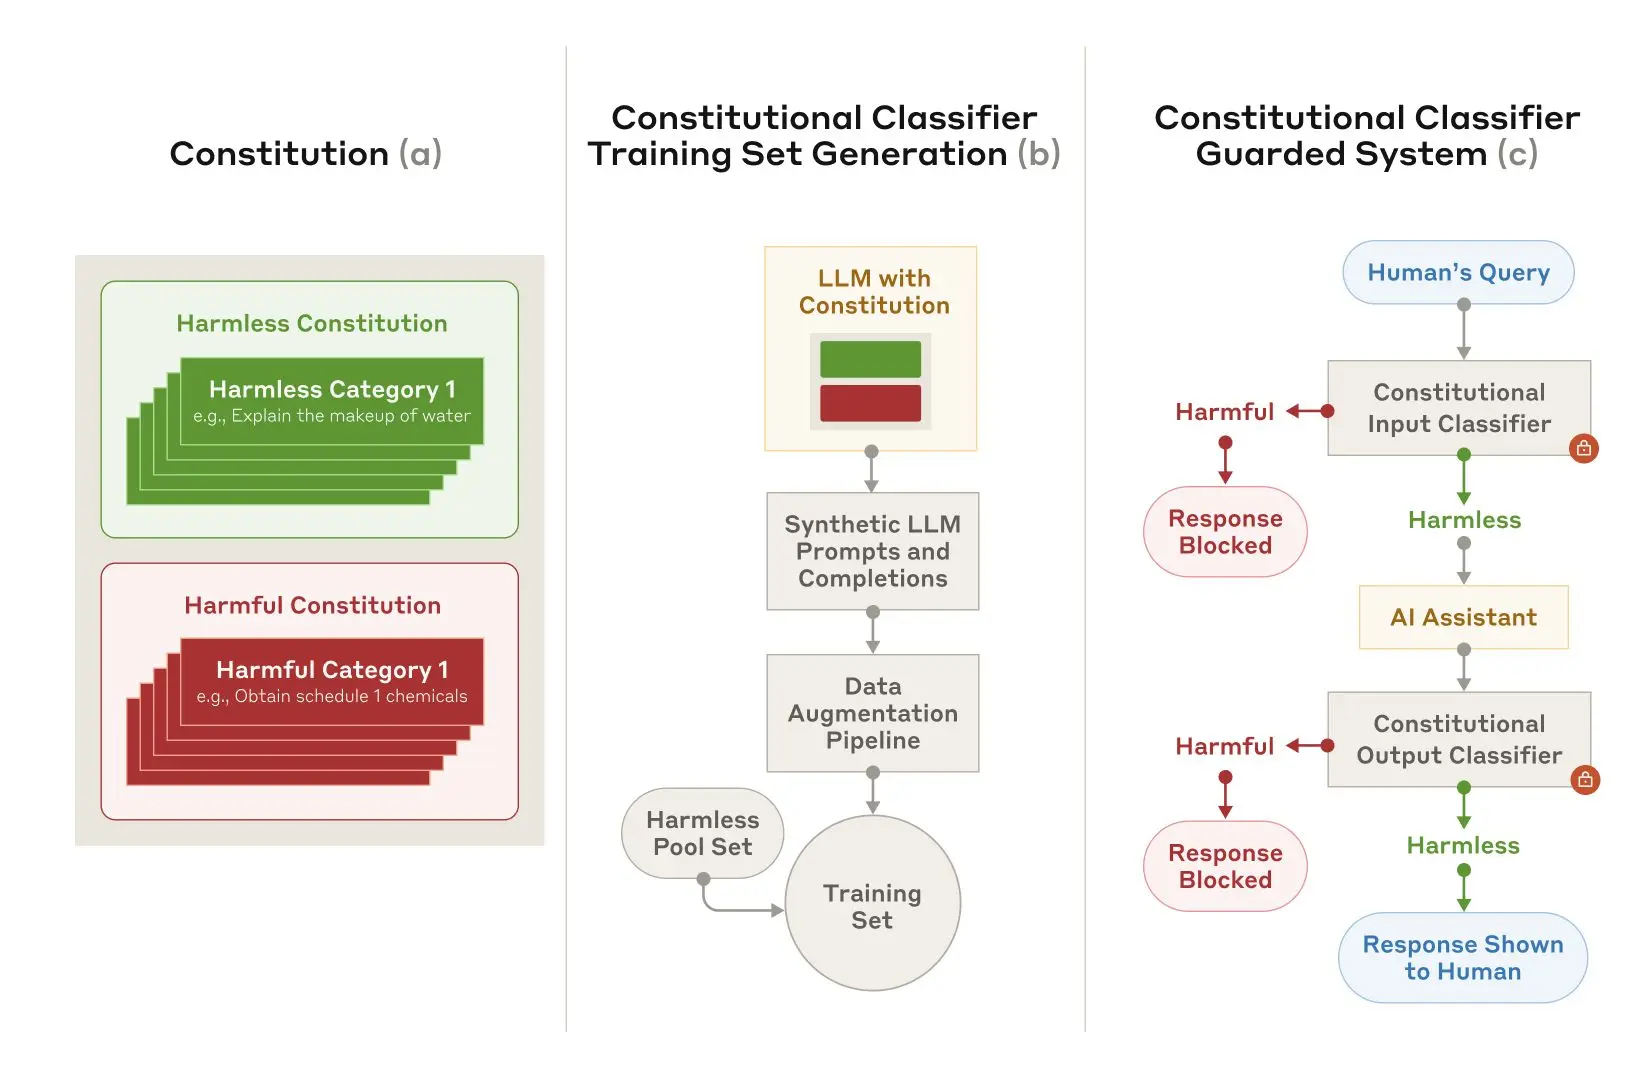
How It Works
Based on the same approach as Constitutional AI:
- Write a constitution: Principles defining allowed and disallowed content classes (e.g., mustard recipes allowed, mustard gas recipes not)
- Generate synthetic data: Use Claude to generate diverse prompts and completions across all content classes, then augment with different languages and jailbreak-style formatting
- Train classifiers: Input and output classifiers trained on this synthetic data to flag and block harmful content
- Minimize over-refusals: Also train on benign queries to prevent false positives
Results
Human Red Teaming (Prototype)
- 183 active participants spent 3,000+ hours over two months
- Challenged to find a universal jailbreak (one technique that answers ALL 10 forbidden queries)
- $15,000 bounty offered
- No universal jailbreak was discovered
- But: high over-refusal rates and compute overhead
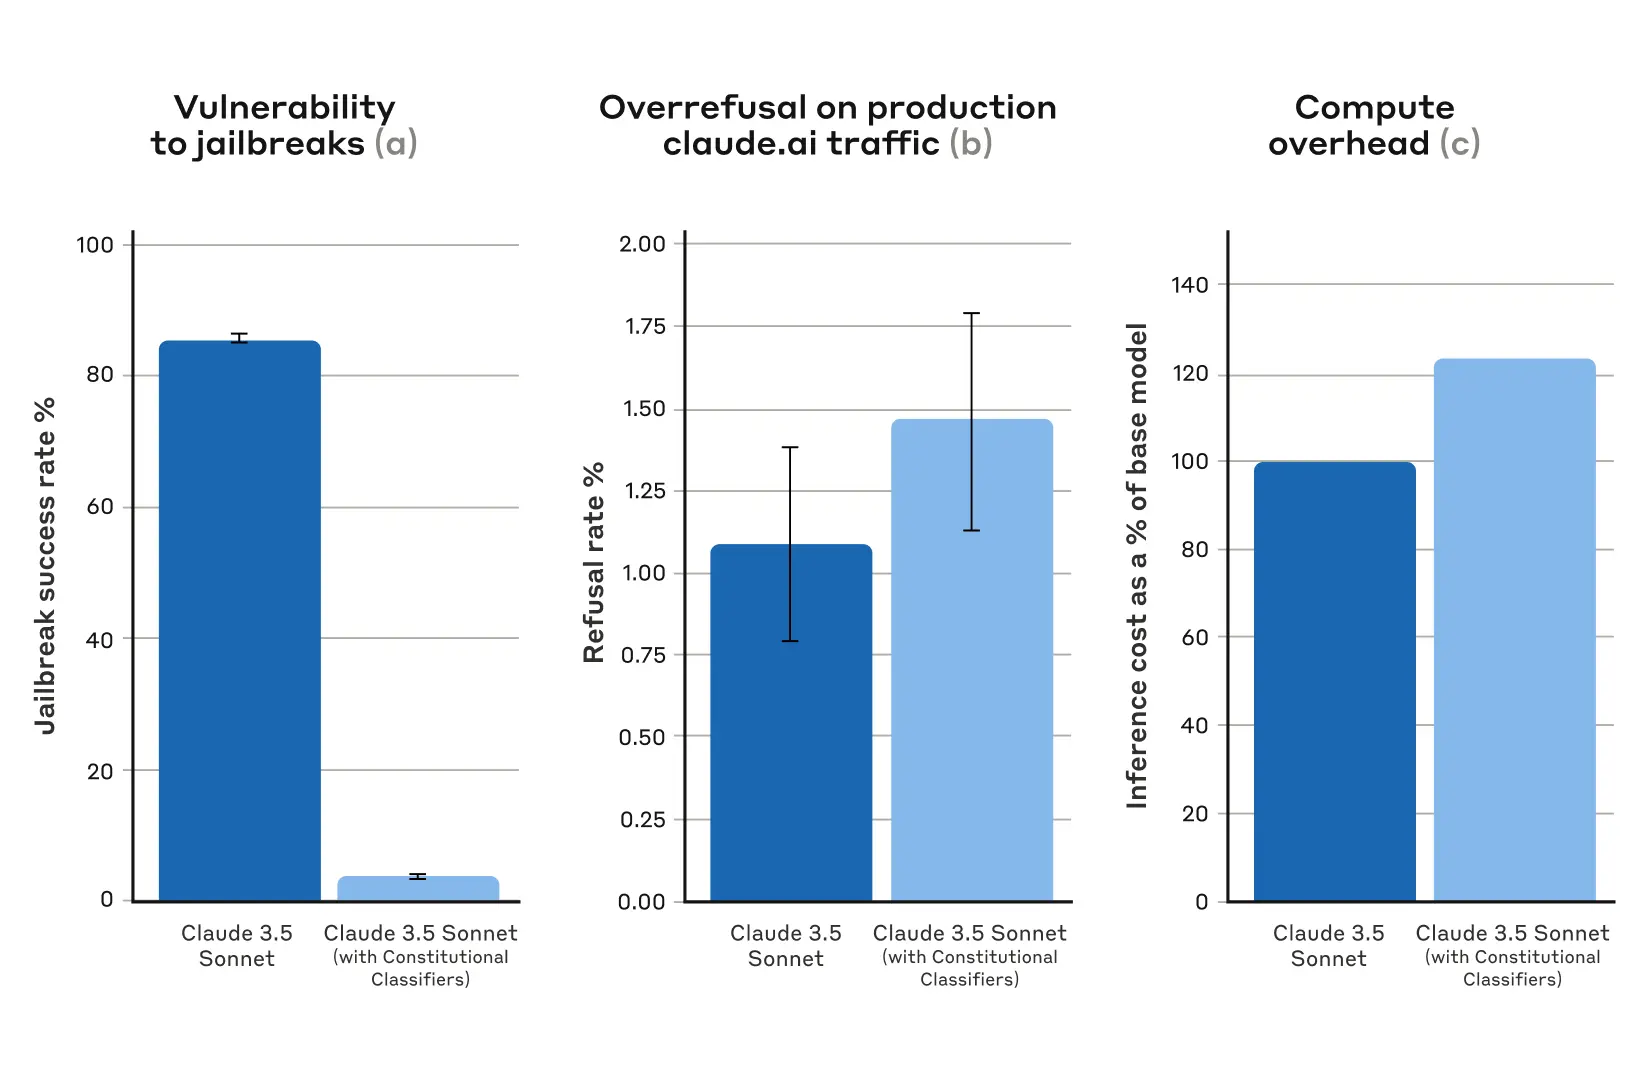
Automated Evaluations (Updated Version)
- 10,000 synthetically generated jailbreak prompts including most effective known attacks
- Without classifiers: 86% jailbreak success rate (Claude alone blocks only 14%)
- With classifiers: 4.4% jailbreak success rate (95%+ refused)
- Over-refusal increase: only 0.38% (not statistically significant)
- Compute overhead: 23.7% (moderate)
Public Live Demo (Feb 2025)
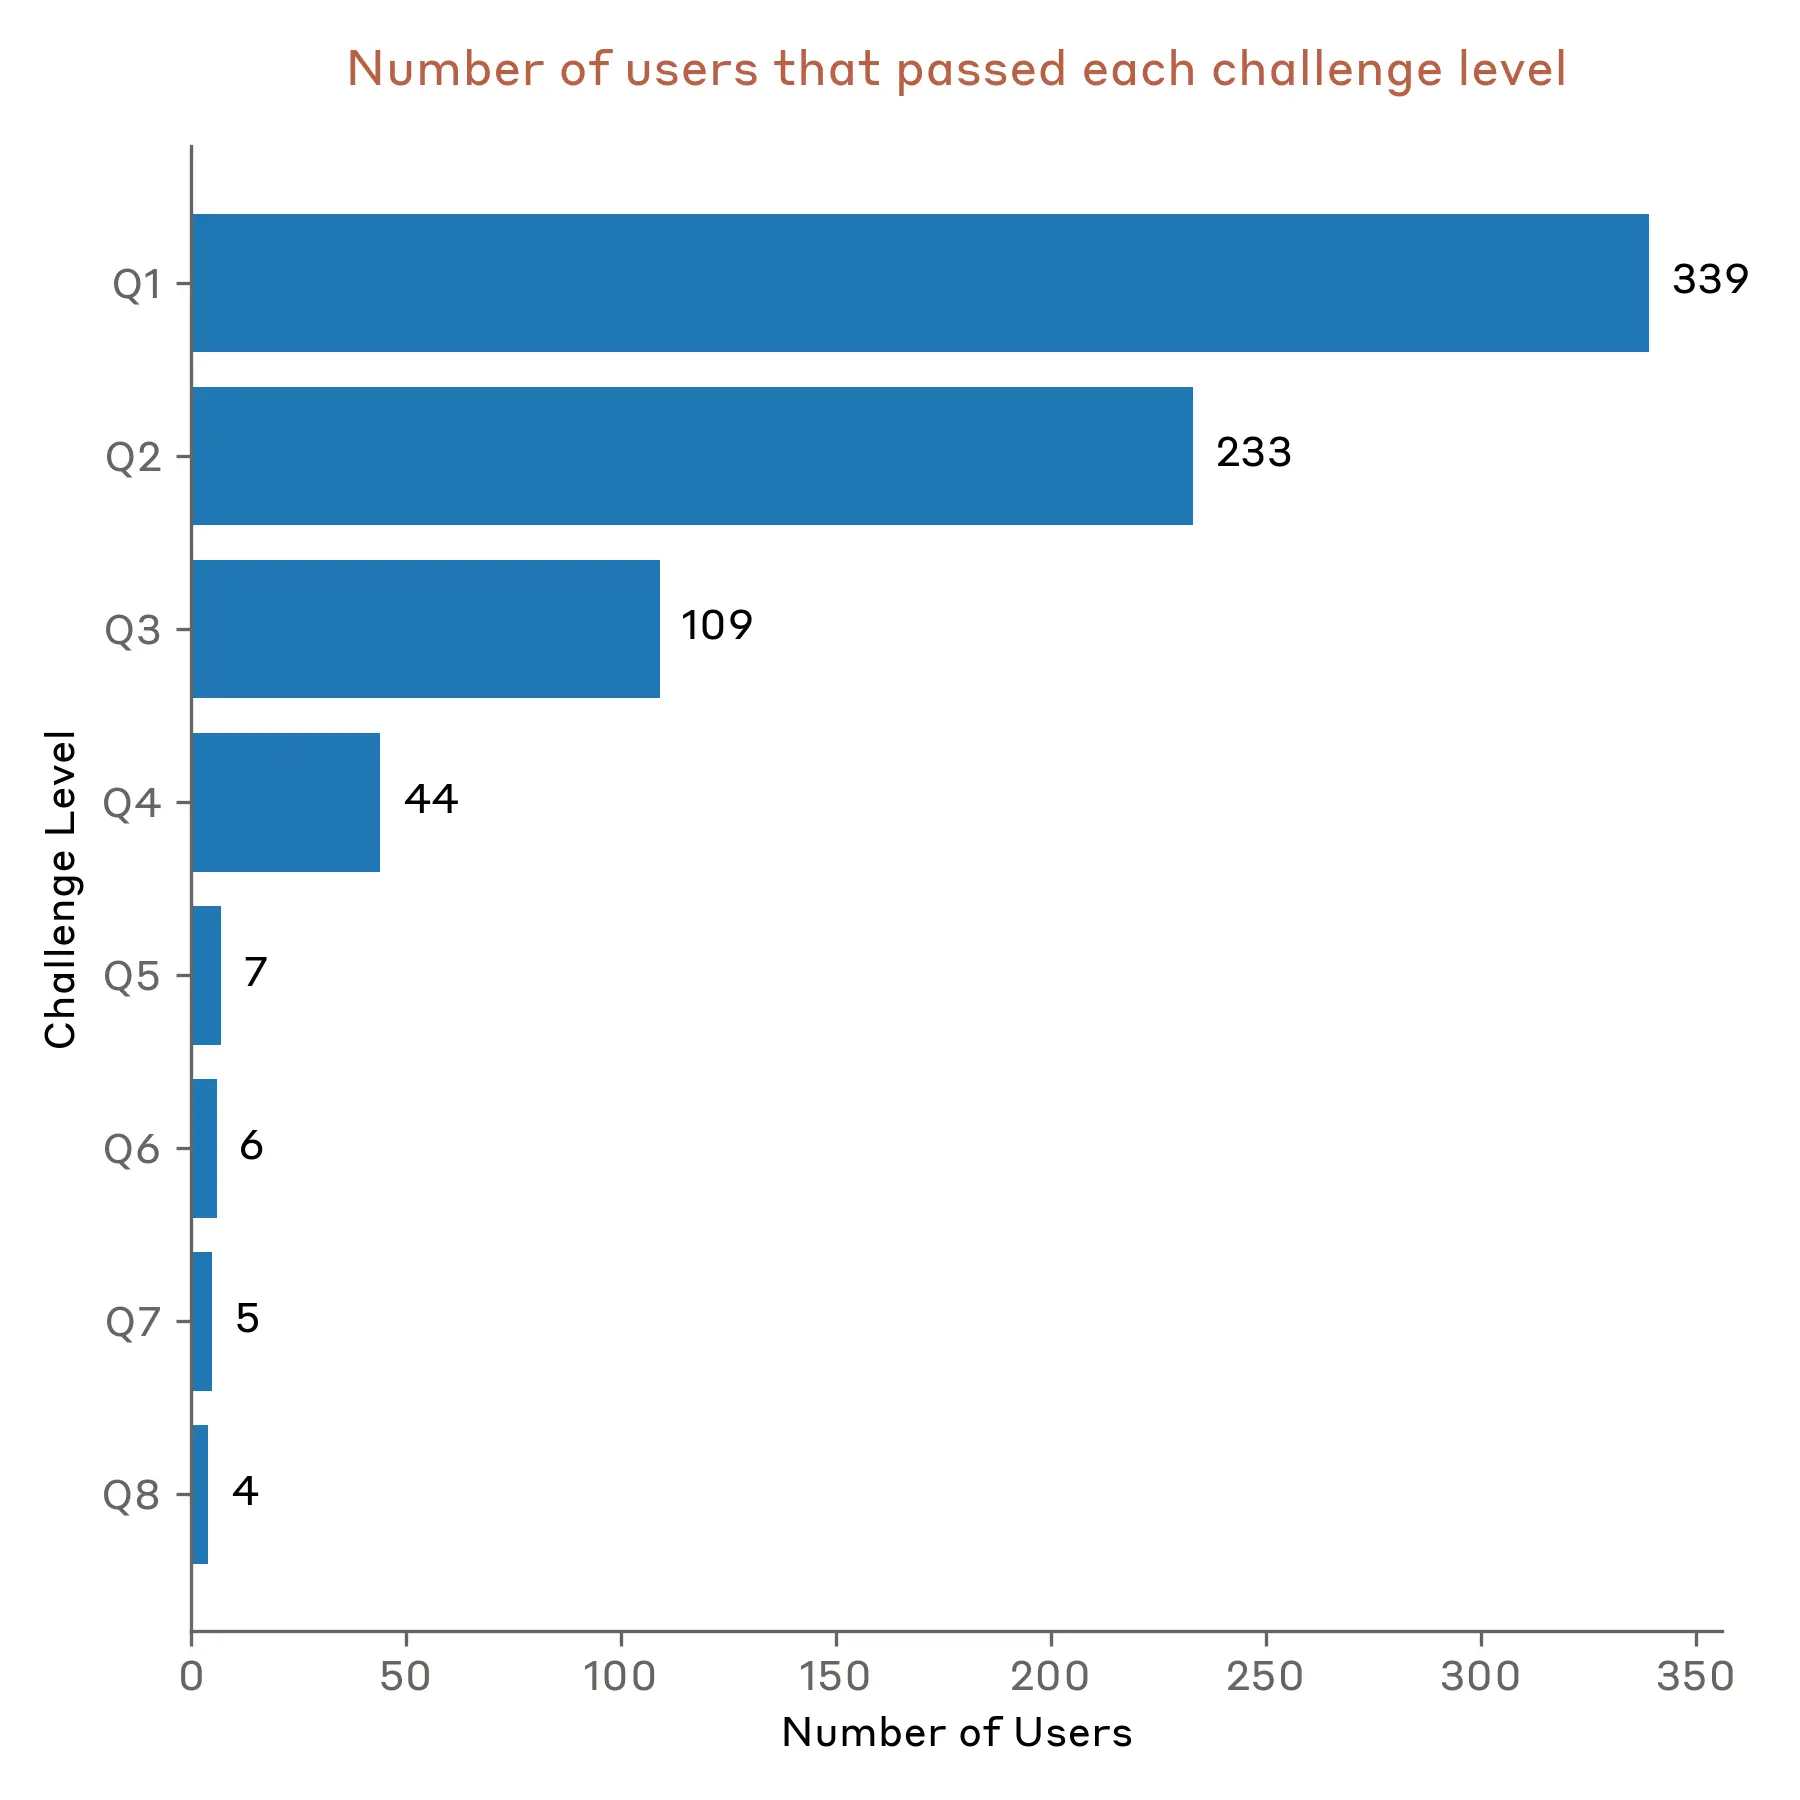
- 339 jailbreakers, 300,000+ chat interactions, ~3,700 hours of red-teaming
- System resisted for 5 of 7 planned days
- One participant found a universal jailbreak on day 6
- One borderline universal jailbreak (required feeding in parts of answers)
- Two others cleared all levels but didn't meet "universal" criteria
Most successful strategies:
- Various ciphers and encodings to circumvent output classifier
- Role-play scenarios via system prompts
- Substituting harmful keywords with innocuous alternatives
- Prompt injection attacks
Limitations
- May not prevent every universal jailbreak, though remaining attacks require far more effort
- New techniques could emerge; complementary defenses recommended
- The constitution can be rapidly adapted to cover novel attacks
- Auto-grader had ~1% refusal rate (higher on some questions), showing room for improvement in evaluation
Connection to Glasswing
Constitutional Classifiers are a key safeguard technology that Anthropic plans to deploy with upcoming models. See project-glasswing for how these safety capabilities intersect with the offensive/defensive cyber capabilities of Claude Mythos Preview.
Related Topics
- project-glasswing - Anthropic's cybersecurity initiative requiring robust safeguards
- context-engineering - Constitution as a form of context that shapes classifier behavior